Papers with Code 아카이브

Scene Text Detection

태스크의 하위 분류와 논문·코드·평가·기법·데이터셋을 탐색하세요.

하위 태스크
2
평가표
9
보존된 평가 기록
146

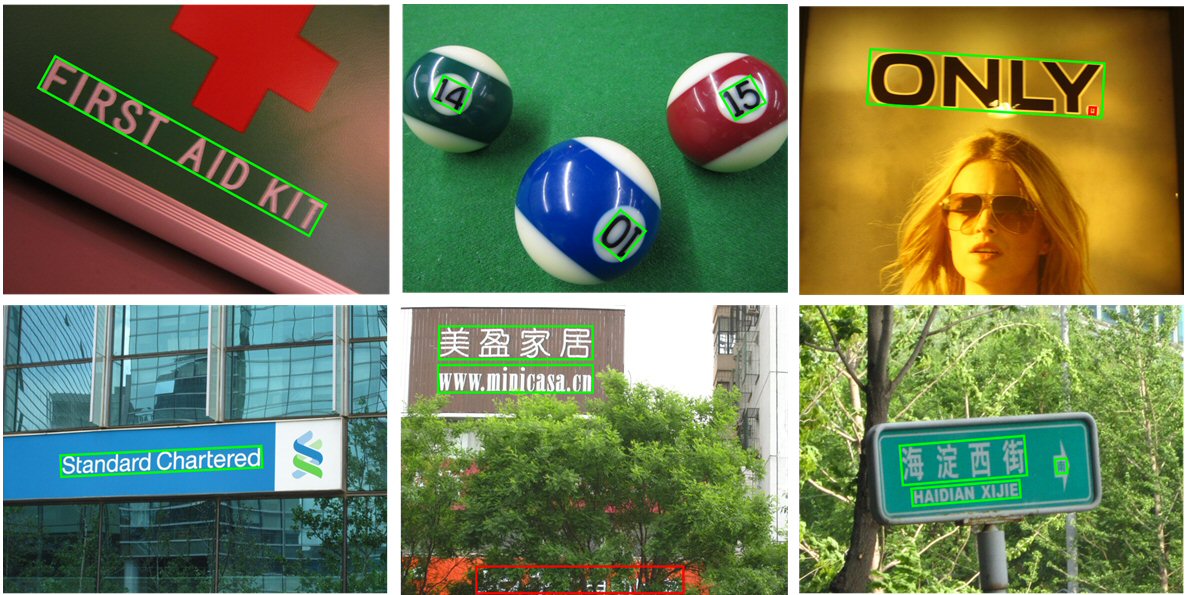
Scene Text Detection is a computer vision task that involves automatically identifying and localizing text within natural images or videos. The goal of scene text detection is to develop algorithms that can robustly detect and and label text with bounding boxes in uncontrolled and complex environments, such as street signs, billboards, or license plates.

Source: ContourNet: Taking a Further Step toward Accurate Arbitrary-shaped Scene Text Detection

데이터셋

출처에 같은 태스크 이름으로 연결된 데이터셋입니다. 동명 태스크가 포함될 수 있으므로, 비교할 때는 평가 결과의 조건도 확인하세요.

COCO-Text

The COCO-Text dataset is a dataset for text detection and recognition. It is based on the MS COCO dataset, which contains images of complex everyday scenes. The COCO-Text dataset contains non-text images, legible text images and illegible text images. In total there are 22184 training images and 7026 validation images with at least one instance of legible text. Source: Improving Text Proposals for Scene Images with Fully Convolutional Networks Image Source: https://vision.cornell.edu/se3/coco-text-2/

ICDAR 2015

ICDAR 2015 was a scene text detection used for the ICDAR 2015 conference.

TextOCR

TextOCR is a dataset to benchmark text recognition on arbitrary shaped scene-text. TextOCR requires models to perform text-recognition on arbitrary shaped scene-text present on natural images. TextOCR provides ~1M high quality word annotations on TextVQA images allowing application of end-to-end reasoning on downstream tasks such as visual question answering or image captioning. Dataset statistics: - 28,134 natural images from TextVQA - 903,069 annotated scene-text words - 32 words per image on average

RCTW-17

Features a large-scale dataset with 12,263 annotated images. Two tasks, namely text localization and end-to-end recognition, are set up. The competition took place from January 20 to May 31, 2017. 23 valid submissions were received from 19 teams. Source: ICDAR2017 Competition on Reading Chinese Text in the Wild (RCTW-17)

Chinese Text in the Wild

Chinese Text in the Wild is a dataset of Chinese text with about 1 million Chinese characters from 3850 unique ones annotated by experts in over 30000 street view images. This is a challenging dataset with good diversity containing planar text, raised text, text under poor illumination, distant text, partially occluded text, etc.

PKU (License Plate Detection)

The PKU dataset has almost 4,000 images categorized into five groups (G1-G5) that show different situations. For example, G1 has images of highways during the day with only one car in them. On the other hand, G5 has images of crosswalks during the day or at night with multiple cars and license plates (LPs). It can be used to train and test LP detectors, as the authors labeled the position of each visible LP on each image.

ShopSign

A newly developed natural scene text dataset of Chinese shop signs in street views. Source: ShopSign: a Diverse Scene Text Dataset of Chinese Shop Signs in Street Views

UrduDoc

The UrduDoc Dataset is a benchmark dataset for Urdu text line detection in scanned documents. It is created as a byproduct of the UTRSet-Real dataset generation process. Comprising 478 diverse images collected from various sources such as books, documents, manuscripts, and newspapers, it offers a valuable resource for research in Urdu document analysis. It includes 358 pages for training and 120 pages for validation, featuring a wide range of styles, scales, and lighting conditions. It serves as a benchmark for evaluating printed Urdu text detection models, and the benchmark results of state-of-the-art models are provided. The Contour-Net model demonstrates the best performance in terms of h-mean. The UrduDoc dataset is the first of its kind for printed Urdu text line detection and will advance research in the field. It will be made publicly available for non-commercial, academic, and research purposes upon request and execution of a no-cost license agreement. To request the dataset and for more information and details about the UrduDoc , UTRSet-Real & UTRSet-Synth datasets, please refer to the Project Website of our paper "UTRNet: High-Resolution Urdu Text Recognition In Printed Documents"

CNTD

Chinese and Naxi scene text detection data set, labelme to json. Source:CNTD

Indian Number Plates Dataset | Vehicle Number Plates | English OCR Detection

This dataset is an extremely challenging set of over 20,000+ original Number plate images captured and crowdsourced from over 700+ urban and rural areas, where each image is manually reviewed and verified by computer vision professionals at Datacluster Labs Dataset Features - Dataset size : 20,000+ - Captured by : Over 4000+ crowdsource contributors - Resolution : 100% of images HD and above (1920x1080 and above) - Location : Captured with 700+ cities and villages across India - Diversity : Various lighting conditions like day, night, varied distances, view points etc. - Device used : Captured using mobile phones in 2020-2022 - Usage : Number plate detection, ANPR, Number plate recognition, Self driving system, etc. Available Annotation formats - COCO, YOLO, PASCAL-VOC, Tf-Record To download full datasets or to submit a request for your dataset needs, please ping us at sales@datacluster.ai Visit www.datacluster.ai to know more.

Media-Text

Media-Text dataset comprising images of banners, posters, covers and another images characterised for media industry. ### DATASET DESCRIPTION - 400 images - 7 744 annotated text instances - 973 annotations have been marked as illegible for the task of text recognition - 659 texts have been markes as do not care (###) for scene text detection. - Images are represented by 193 unique resolutions. Annotation Format - Each image has corresponding gt_*.txt file, which contains annotations in bounding box format (defined by 4 courners), transcription, and bool flag which determines that text is illegible for OCR. Proposed format is similar to ICDAR15 annotations. x1, x2, ..., x4, y4, transcription, OCR Flag **Example: ** 37,68,198,49,214,181,52,200,LADIES,False **Full paper: ** ResearchGate Please cite the related works in your publications if it helps your research: <br> S. Kalisz, M. Marczyk, J. Polańska, and R. Fagas, “Media-text: a media industry-based dataset for scene text detection,” in Modelling and simulation 2024. The 2024 European Simulation and Modelling Conference, M. Graña and J. D. Nuñez-Gonzalez, Eds., EUROSIS-ETI, 2024, pp. 138–144.
SignboardText

This dataset contains images and annotations for scene text detection and recognition. It is made up of two parts: (1) 1,175 images manually labeled with a total of 59,588 text instances at the line and word levels; and (2) 929 signboard images collected from the VinText, Total-Text, and ICDAR15 datasets. Each text instance in the first part of our dataset has a quadrilateral bounding box and a ground truth character sequence associated with it. In the second part, images are selected if they contain signboards. This portion of the dataset comprises 20,261 text instances at word levels. This brings the total text instances in our final dataset up to 79,814. Following the ICDAR15 standard, we annotated each image with all of the text instances, polygons, and content that were present. Manual annotations were done on each and every image.

출처: Papers with Code · CC BY-SA 4.0. 아카이브 자료와 새로 수집한 논문은 별도로 관리합니다.