Papers with Code 아카이브

Mathematical Reasoning

태스크의 하위 분류와 논문·코드·평가·기법·데이터셋을 탐색하세요.

하위 태스크
7
평가표
11
보존된 평가 기록
41

데이터셋

출처에 같은 태스크 이름으로 연결된 데이터셋입니다. 동명 태스크가 포함될 수 있으므로, 비교할 때는 평가 결과의 조건도 확인하세요.

GSM8K

GSM8K is a dataset of 8.5K high quality linguistically diverse grade school math word problems created by human problem writers. The dataset is segmented into 7.5K training problems and 1K test problems. These problems take between 2 and 8 steps to solve, and solutions primarily involve performing a sequence of elementary calculations using basic arithmetic operations (+ − ×÷) to reach the final answer. A bright middle school student should be able to solve every problem. It can be used for multi-step mathematical reasoning. Image source: https://arxiv.org/pdf/2110.14168v1.pdf

MATH

MATH is a new dataset of 12,500 challenging competition mathematics problems. Each problem in MATH has a full step-by-step solution which can be used to teach models to generate answer derivations and explanations. Source: Hendrycks et al. Image source: Hendrycks et al.

SVAMP

A challenge set for elementary-level Math Word Problems (MWP). An MWP consists of a short Natural Language narrative that describes a state of the world and poses a question about some unknown quantities. The examples in SVAMP test a model across different aspects of solving MWPs: 1) Is the model question sensitive? 2) Does the model have robust reasoning ability? 3) Is it invariant to structural alterations?

BIG-bench

The Beyond the Imitation Game Benchmark (BIG-bench) is a collaborative benchmark intended to probe large language models and extrapolate their future capabilities. Big-bench include more than 200 tasks. Image source: https://arxiv.org/pdf/2206.04615.pdf

MathVista

MathVista is a consolidated Mathematical reasoning benchmark within Visual contexts. It consists of three newly created datasets, IQTest, FunctionQA, and PaperQA, which address the missing visual domains and are tailored to evaluate logical reasoning on puzzle test figures, algebraic reasoning over functional plots, and scientific reasoning with academic paper figures, respectively. It also incorporates 9 MathQA datasets and 19 VQA datasets from the literature, which significantly enrich the diversity and complexity of visual perception and mathematical reasoning challenges within our benchmark. In total, MathVista includes 6,141 examples collected from 31 different datasets. - Project: https://mathvista.github.io/ - Visualization: https://mathvista.github.io/#visualization - Leaderboard: https://mathvista.github.io/#leaderboard - Paper: https://arxiv.org/abs/2310.02255 - Data: https://huggingface.co/datasets/AI4Math/MathVista - Code: https://github.com/lupantech/MathVista

MathQA

MathQA significantly enhances the AQuA dataset with fully-specified operational programs. Source: MathQA: Towards Interpretable Math Word Problem Solving with Operation-Based Formalisms

ASDiv

We present ASDiv (Academia Sinica Diverse MWP Dataset), a diverse (in terms of both language patterns and problem types) English math word problem (MWP) corpus for evaluating the capability of various MWP solvers. Existing MWP corpora for studying AI progress remain limited either in language usage patterns or in problem types. We thus present a new English MWP corpus with 2,305 MWPs that cover more text patterns and most problem types taught in elementary school. Each MWP is annotated with its problem type and grade level (for indicating the level of difficulty). Furthermore, we propose a metric to measure the lexicon usage diversity of a given MWP corpus, and demonstrate that ASDiv is more diverse than existing corpora. Experiments show that our proposed corpus reflects the true capability of MWP solvers more faithfully.

MAWPS

MAWPS is an online repository of Math Word Problems, to provide a unified testbed to evaluate different algorithms. MAWPS allows for the automatic construction of datasets with particular characteristics, providing tools for tuning the lexical and template overlap of a dataset as well as for filtering ungrammatical problems from web-sourced corpora. The online nature of this repository facilitates easy community contribution. Amassed 3,320 problems, including the full datasets used in several previous works.

MGSM

Multilingual Grade School Math Benchmark (MGSM) is a benchmark of grade-school math problems. The same 250 problems from GSM8K are each translated via human annotators in 10 languages. GSM8K (Grade School Math 8K) is a dataset of 8.5K high-quality linguistically diverse grade school math word problems. The dataset was created to support the task of question answering on basic mathematical problems that require multi-step reasoning.

Math23K

Math23K is a dataset created for math word problem solving, contains 23, 162 Chinese problems crawled from the Internet. Refer to our paper for more details: The dataset is originally introduced in the paper Deep Neural Solver for Math Word Problems. The original files are originally split into train/test split, while other research efforts (https://github.com/2003pro/Graph2Tree) perform the train/dev/test split.

PrOntoQA

PrOntoQA is a question-answering dataset which generates examples with chains-of-thought that describe the reasoning required to answer the questions correctly. The sentences in the examples are syntactically simple and amenable to semantic parsing. It can be used to formally analyze the predicted chain-of-thought from large language models such as GPT-3. Source: Language Models Are Greedy Reasoners: A Systematic Formal Analysis of Chain-of-Thought Image Source: https://arxiv.org/pdf/2210.01240v1.pdf

GeoQA

GeoQA is a dataset for automatic geometric problem solving containing 5,010 geometric problems with corresponding annotated programs, which illustrate the solving process of the given problems Compared with another publicly available dataset GeoS, GeoQA is 25 times larger, in which the program annotations can provide a practical testbed for future research on explicit and explainable numerical reasoning.

Geometry3K

A new large-scale geometry problem-solving dataset - 3,002 multi-choice geometry problems - dense annotations in formal language for the diagrams and text - 27,213 annotated diagram logic forms (literals) - 6,293 annotated text logic forms (literals)

IconQA

Current visual question answering (VQA) tasks mainly consider answering human-annotated questions for natural images in the daily-life context. Icon question answering (IconQA) is a benchmark which aims to highlight the importance of abstract diagram understanding and comprehensive cognitive reasoning in real-world diagram word problems. For this benchmark, a large-scale IconQA dataset is built that consists of three sub-tasks: multi-image-choice, multi-text-choice, and filling-in-the-blank. Compared to existing VQA benchmarks, IconQA requires not only perception skills like object recognition and text understanding, but also diverse cognitive reasoning skills, such as geometric reasoning, commonsense reasoning, and arithmetic reasoning. Description from: IconQA

TheoremQA

We propose the first question-answering dataset driven by STEM theorems. We annotated 800 QA pairs covering 350+ theorems spanning across Math, EE&CS, Physics and Finance. The dataset is collected by human experts with very high quality. We provide the dataset as a new benchmark to test the limit of large language models to apply theorems to solve challenging university-level questions. We provide a pipeline in the following to prompt LLMs and evaluate their outputs with WolframAlpha.

GeoS

GeoS is a dataset for automatic math problem solving. It is a dataset of SAT plane geometry questions where every question has a textual description in English accompanied by a diagram and multiple choices. Questions and answers are compiled from previous official SAT exams and practice exams offered by the College Board. We annotate ground-truth logical forms for all questions in the dataset.

ALG514

514 algebra word problems and associated equation systems gathered from Algebra.com.

GSM-Plus

By perturbing the widely used GSM8K dataset, an adversarial dataset for grade-school math called GSM-Plus is created. Motivated by the capability taxonomy for solving math problems mentioned in Polya's principles, this paper identifies 5 perspectives to guide the development of GSM-Plus: * Numerical Variation refers to altering the numerical data or its types, including 3 subcategories: Numerical Substitution, Digit Expansion, and Integer-decimal-fraction Conversion. * Arithmetic Variation refers to reversing or introducing additional operations (e.g., addition, subtraction, multiplication, and division) to math problems, including 2 subcategories: Adding Operation and Reversing Operation. * Problem Understanding refers to rephrasing the text description of the math problems. * Distractor Insertion refers to inserting topic-related but useless sentences to the problems. * Critical Thinking focuses on question or doubt ability when the question lacks necessary statements. GSM-Plus can be used to evaluate the robustness of current LLMs in mathematical reasoning.

MathBench

MathBench is an All in One math dataset for language model evaluation, with: A Sophisticated Five-Stage Difficulty Mechanism: Unlike the usual mathematical datasets that can only evaluate a single difficulty level or have a mix of unclear difficulty levels, MathBench provides 3709 questions with a gradient difficulty division by education stages, ranging from basic arithmetic to primary, middle, high school, and college levels, allowing you to get a clear overview of the comprehensive difficulty evaluation results. Bilingual Gradient Evaluation: Apart from the basic calculation part which is language-independent, MathBench provides questions in both Chinese and English for the four-stage difficulty datasets from primary to college. Implementation of the Robust Circular Evaluation (CE) Method: MathBench use CE as the main evaluation method for questions. Compared to the general Accuracy evaluation method, CE requires the model to answer the same multiple-choice question multiple times, with the order of the options changing each time. The model is considered correct on this question only if all answers are correct. The results of CE can reflect the model's capabilities more realistically, providing more valuable evaluation results. Support for Basic Theory Questions: For every stage, MathBench provides questions that cover the basic theory knowledge points of the corresponding stage, to ascertain whether the model has genuinely mastered the fundamental concepts of each stage or merely memorized the answers.

PGPS9K

A new large scale plane geometry problem solving dataset called PGPS9K, labeled both fine-grained diagram annotation and interpretable solution program.

Lila

Lila is a unified mathematical reasoning benchmark consisting of 23 diverse tasks along four dimensions: (i) mathematical abilities e.g., arithmetic, calculus (ii) language format e.g., question-answering, fill-in-the-blanks (iii) language diversity e.g., no language, simple language (iv) external knowledge e.g., commonsense, physics. The benchmark is constructed by extending 20 datasets benchmark by collecting task instructions and solutions in the form of Python programs, thereby obtaining explainable solutions in addition to the correct answer.

MATH-V

Math-Vision (Math-V) dataset is a meticulously curated collection of 3,040 high-quality mathematical problems with visual contexts sourced from real math competitions. Spanning 16 distinct mathematical disciplines and graded across 5 levels of difficulty, our dataset provides a comprehensive and diverse set of challenges for evaluating the mathematical reasoning abilities of LMMs. Through extensive experimentation, we unveil a notable performance gap between current LMMs and human performance on Math-Vision, underscoring the imperative for further advancements in LMMs. Moreover, our detailed categorization allows for a thorough error analysis of LMMs, offering valuable insights to guide future research and development.

CriticBench

CriticBench is a comprehensive benchmark designed to assess the abilities of Large Language Models (LLMs) to critique and rectify their reasoning across various tasks. It encompasses five reasoning domains: 1. Mathematical 2. Commonsense 3. Symbolic 4. Coding 5. Algorithmic CriticBench compiles 15 datasets and incorporates responses from three LLM families. By utilizing CriticBench, researchers evaluate and dissect the performance of 17 LLMs in generation, critique, and correction reasoning (referred to as GQC reasoning). Notable findings include: 1. A linear relationship in GQC capabilities, with critique-focused training significantly enhancing performance. 2. Task-dependent variation in correction effectiveness, with logic-oriented tasks being more amenable to correction. 3. GQC knowledge inconsistencies that decrease as model size increases. 4. An intriguing inter-model critiquing dynamic, where stronger models excel at critiquing weaker ones, while weaker models surprisingly surpass stronger ones in self-critique. (1) CriticBench: Benchmarking LLMs for Critique-Correct Reasoning. https://arxiv.org/abs/2402.14809. (2) CriticBench: Benchmarking LLMs for Critique-Correct Reasoning. http://export.arxiv.org/abs/2402.14809. (3) CriticBench: Benchmarking LLMs for Critique-Correct Reasoning. https://openreview.net/forum?id=sc5i7q6DQO. (4) CriticBench: Benchmarking LLMs for Critique-Correct Reasoning - arXiv.org. https://arxiv.org/html/2402.14809v2. (5) undefined. https://doi.org/10.48550/arXiv.2402.14809.

CLEVR-Math

CLEVR-Math is a multi-modal math word problems dataset consisting of simple math word problems involving addition/subtraction, represented partly by a textual description and partly by an image illustrating the scenario. These word problems requires a combination of language, visual and mathematical reasoning.

PEN

  • Provided explanations on the existing three benchmark datasets on solving algebraic word problems: ALG514, DRAW-1K, MAWPS

DRAW-1K

DRAW-1K is a dataset consisting of 1000 algebra word problems, semiautomatically annotated for the evaluation of automatic solvers. DRAW includes gold coefficient alignments that are necessary uniquely identify the derivation of an equation system.

Mindgames

We generate epistemic reasoning problems using modal logic to target theory of mind (tom) in natural language processing models.

DART-Math-Hard

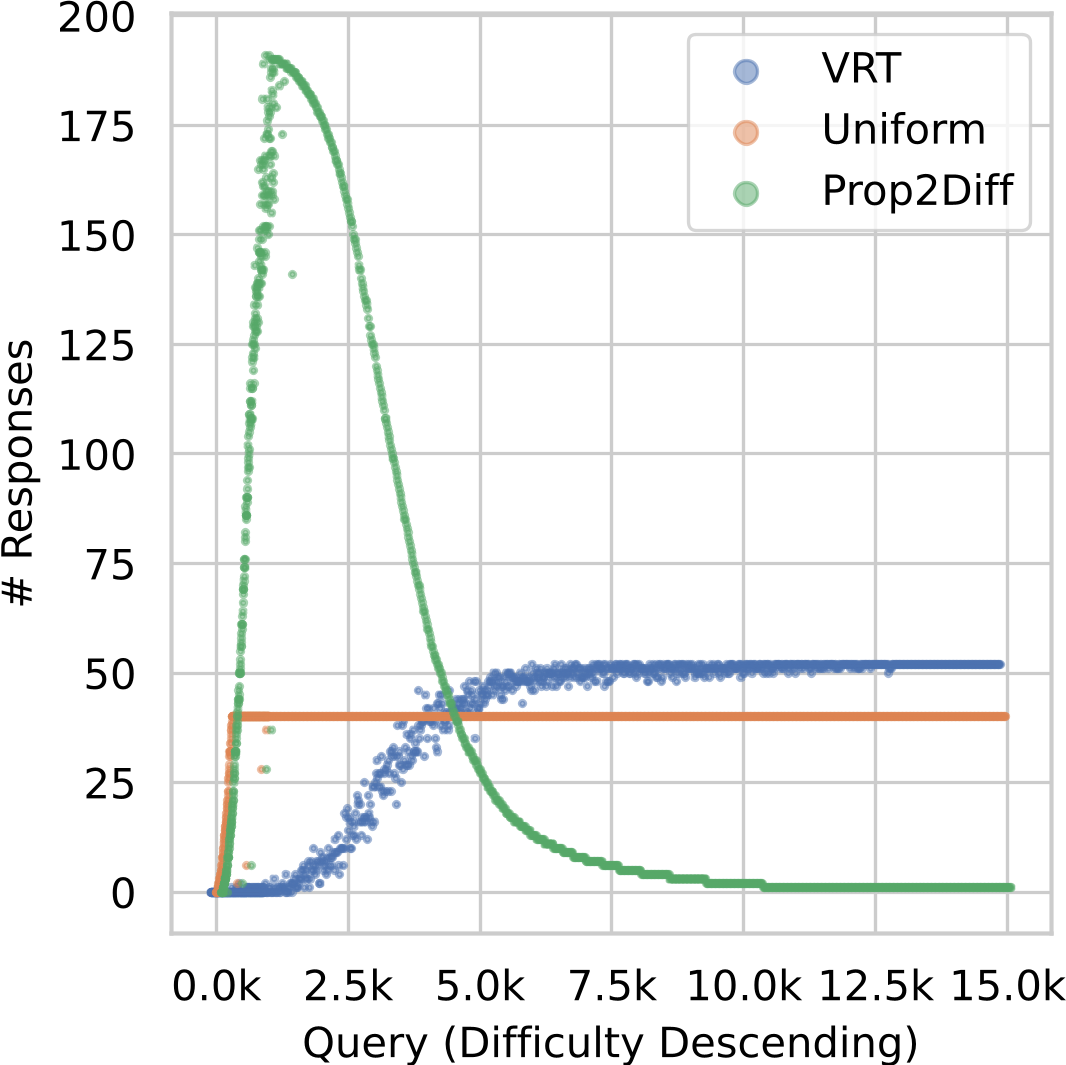
🎯 DART-Math > Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving 📝 Paper@arXiv | 🤗 Datasets&Models@HF | 🐱 Code@GitHub 🐦 Thread@X(Twitter) | 🐶 中文博客@知乎 | 📊 Leaderboard@PapersWithCode | 📑 BibTeX ## Datasets: DART-Math DART-Math datasets are the state-of-the-art and data-efficient open-source instruction tuning datasets for mathematical reasoning. DART-Math-Hard contains ~585k mathematical QA pair samples constructed by applying DARS-Prop2Diff to the query set from MATH and GSK8K training sets, achieves SOTA on many challenging mathematical reasoning benchmarks. It introduces a deliberate bias towards hard queries, opposite to vanilla rejection sampling. Performance produced by DART-Math-Hard is usually but not necessarily slightly better (~1% absolutely) than DART-Math-Uniform, which contains ~591k samples constructed by applying DARS-Uniform. ### Comparison between Mathematical Instruction Tuning Datasets Most of previous datasets are constructed with ChatGPT, and many of them are not open-source, especially for ones of the best performance. | Math SFT Dataset | # of Samples | MATH | GSM8K | College | Synthesis Agent(s) | Open-Source | | :--------------------------------------------------------------------------------- | -----------: | -----------------------------------------------------------------: | ---------------------------------------------: | -----------------------------------------------------------------------------------------------------------: | :---------------------- | :-------------------------------------------------------------------------: | | WizardMath | 96k | 32.3 | 80.4 | 23.1 | GPT-4 | ✗ | | MetaMathQA | 395k | 29.8 | 76.5 | 19.3 | GPT-3.5 | ✓ | | MMIQC | 2294k | 37.4 | 75.4 | 28.5 | GPT-4+GPT-3.5+Human | ✓ | | Orca-Math | 200k | -- | -- | -- | GPT-4 | ✓ | | Xwin-Math-V1.1 | 1440k | 45.5 | 84.9 | 27.6 | GPT-4 | ✗ | | KPMath-Plus | 1576k | 46.8 | 82.1 | -– | GPT-4 | ✗ | | MathScaleQA | 2021k | 35.2 | 74.8 | 21.8 | GPT-3.5+Human | ✗ | | DART-Math-Uniform | 591k | 43.5 | 82.6 | 26.9 | DeepSeekMath-7B-RL | ✓ | | DART-Math-Hard | 585k | 45.5 | 81.1 | 29.4 | DeepSeekMath-7B-RL | ✓ | <sup>MATH and GSM8K are in-domain, while College(Math) is out-of-domain. Performance here are of models fine-tuned from Mistral-7B, except for Xwin-Math-V1.1 based on Llama2-7B. Bold/Italic means the best/second best score here.</sup> ## Dataset Construction: DARS - Difficulty-Aware Rejection Sampling Previous works usually synthesize data from proprietary models to augment existing datasets, followed by instruction tuning to achieve top-tier results. However, our analysis of these datasets reveals severe biases towards easy queries, with frequent failures to generate any correct response for the most challenging queries. Motivated by the observation above, we propose to Difficulty-Aware Rejection Sampling (DARS), to collect more responses for more difficult queries. Specifically, we introduce two strategies to increase the number of correct responses for difficult queries: 1) Uniform, which involves sampling responses for each query until each query accumulates $k_u$ correct responses, where $k_u$ is a preset hyperparameter determined by the desired size of the synthetic dataset; 2) Prop2Diff, where we continue sampling responses until the number of correct responses for each query is proportional to its difficulty score. The most challenging queries will receive $k_p$ responses and kp is a hyperparameter. This method introduces a deliberate bias in the opposite direction to vanilla rejection sampling, towards more difficult queries, inspired by previous works that demonstrate difficult samples can be more effective to enhance model capabilities (Sorscher et al., 2022; Liu et al., 2024b). See Figure 1 (Right) for examples of DART-Math-Uniform by DARS-Uniform and DART-Math-Hard by DARS-Prop2Diff. ## Citation If you find our data, model or code useful for your work, please kindly cite our paper: latex @article{tong2024dartmath, title={DART-Math: Difficulty-Aware Rejection Tuning for Mathematical Problem-Solving}, author={Yuxuan Tong and Xiwen Zhang and Rui Wang and Ruidong Wu and Junxian He}, year={2024}, eprint={2407.13690}, archivePrefix={arXiv}, primaryClass={cs.CL}, url={https://arxiv.org/abs/2407.13690}, }

MGSM8KInstruct

MGSM8KInstruct, the multilingual math reasoning instruction dataset, encompassing ten distinct languages, thus addressing the issue of training data scarcity in multilingual math reasoning.

ParaMAWPS

This repository contains the code, data, and models of the paper titled "Math Word Problem Solving by Generating Linguistic Variants of Problem Statements" published in the Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 4: Student Research Workshop). The work is outlined in a more detailed and expository manner in our Bachelor of Science (B.Sc.) thesis titled "Variational Mathematical Reasoning: Enhancing Math Word Problem Solvers with Linguistic Variants and Disentangled Attention" which can be accessed from the Islamic University of Technology (IUT) Institutional Repository. arXiv anthology GoogleScholar ResearchGate HuggingFace PDF Slides Video Poster Thesis License: Creative Commons Attribution-NonCommercial-ShareAlike 4.0 International license ## Dataset In order to download our dataset PᴀʀᴀMAWPS, please navigate to the ParaMAWPS folder. We use an $80:10:10$ train-validation-test split for our PᴀʀᴀMAWPS dataset. The splits are available in .json format in the aforementioned folder. ### Data Format Each row consists of a Math Word Problem (MWP). The table below describes what each column signifies. Column Title | Description ------------ | ------------- id | The unique identification number of the sample. Seed problems have id size of $\leq 4$, whereas, variant problems have id size of $> 4$. The last variant of a seed problem (generally with the id "$16000i$", where $i$ is the id of the seed problem) is the inverse variant of the seed problem. original_text | The problem statement of the MWP. The seed problems have the same problem statement as present in the Mᴀᴡᴘs dataset. equation | The equation with a variable \(x\) which solves the MWP quantity_tagged_text | The problem statement of the MWP, where each quantity is replaced with a unique tag \([Q_i]\) quantity_tagged_equation | The equation with a variable \(x\) which solves the MWP, but each quantity is replaced with its unique tag \([Q_i]\) in the problem statement have_constant | Whether the use of a constant value is required to solve the MWP <br> For an MWP sample \(i\) with have_constant label \(C_i\), the boolean label is,<br>$C_i =\begin{cases} \text{FALSE}, & \text{if $i$ requires $0$ constant values}\\\ \text{TRUE}, & \text{if $i$ requires $\geq 1$ constant values}\end{cases}$ ## Types of Variations <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_variationtypes.png" alt="drawing" style="width:1000px;"/> ## Dataset Statistics <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_datasetcomparisontable.png" alt="drawing" style="width:500px;"/> <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_datasetcomparisongraph.png" alt="drawing" style="width:500px;"/> # Methodology <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_architecture2.png" alt="drawing" style="width:1000px;"/> # Results To reproduce the results, please refer to the documentation of MWPToolkit created by Yihuai Lan et al. <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_results.png" alt="drawing" style="width:500px;"/> <img src="https://github.com/Starscream-11813/Variational-Mathematical-Reasoning/raw/main/images/ACLMWP_ablation.png" alt="drawing" style="width:500px;"/> ## Citation If you find this work useful, please cite our paper: bib @inproceedings{raiyan-etal-2023-math, title = "Math Word Problem Solving by Generating Linguistic Variants of Problem Statements", author = "Raiyan, Syed Rifat and Faiyaz, Md Nafis and Kabir, Shah Md. Jawad and Kabir, Mohsinul and Mahmud, Hasan and Hasan, Md Kamrul", booktitle = "Proceedings of the 61st Annual Meeting of the Association for Computational Linguistics (Volume 4: Student Research Workshop)", month = jul, year = "2023", address = "Toronto, Canada", publisher = "Association for Computational Linguistics", url = "https://aclanthology.org/2023.acl-srw.49", doi = "10.18653/v1/2023.acl-srw.49", pages = "362--378", abstract = "The art of mathematical reasoning stands as a fundamental pillar of intellectual progress and is a central catalyst in cultivating human ingenuity. Researchers have recently published a plethora of works centered around the task of solving Math Word Problems (MWP) {---} a crucial stride towards general AI. These existing models are susceptible to dependency on shallow heuristics and spurious correlations to derive the solution expressions. In order to ameliorate this issue, in this paper, we propose a framework for MWP solvers based on the generation of linguistic variants of the problem text. The approach involves solving each of the variant problems and electing the predicted expression with the majority of the votes. We use DeBERTa (Decoding-enhanced BERT with disentangled attention) as the encoder to leverage its rich textual representations and enhanced mask decoder to construct the solution expressions. Furthermore, we introduce a challenging dataset, ParaMAWPS, consisting of paraphrased, adversarial, and inverse variants of selectively sampled MWPs from the benchmark Mawps dataset. We extensively experiment on this dataset along with other benchmark datasets using some baseline MWP solver models. We show that training on linguistic variants of problem statements and voting on candidate predictions improve the mathematical reasoning and robustness of the model. We make our code and data publicly available.", } You can also cite our thesis: bib @phdthesis{raiyan2023variational, type={Bachelor's Thesis}, title={Variational Mathematical Reasoning: Enhancing Math Word Problem Solvers with Linguistic Variants and Disentangled Attention}, author={Raiyan, Syed Rifat and Faiyaz, Md Nafis and Kabir, Shah Md Jawad}, year={2023}, school={Department of Computer Science and Engineering (CSE), Islamic University of Technology}, address={Board Bazar, Gazipur-1704, Dhaka, Bangladesh}, note={Available at \url{http://103.82.172.44:8080/xmlui/handle/123456789/2092}} }
QUITE

QUITE (Quantifying Uncertainty in natural language Text) is an entirely new benchmark that allows for assessing the capabilities of neural language model-based systems w.r.t. to Bayesian reasoning on a large set of input text that describes probabilistic relationships in natural language text.

ASyMOB

ASyMOB (pronounced Asimov, in tribute to the renowned author), is a novel assessment framework focused exclusively on symbolic manipulation, featuring 17,092 unique math challenges, organized by similarity and complexity. ASyMOB enables analysis of LLM failure root-causes and generalization capabilities by comparing performance in problems that differ by simple numerical or symbolic "perturbations".

CHAMP

The Concept and Hint-Annotated Math Problems (CHAMP) consists of high school math competition problems, annotated with concepts, or general math facts, and hints, or problem-specific tricks. These annotations allow us to explore the effects of additional information, such as relevant hints, misleading concepts, or related problems.

Conic10K

Conic10K is an open-ended math problem dataset on conic sections in Chinese senior high school education. This dataset contains 10,861 carefully annotated problems, each one has a formal representation, the corresponding text spans, the answer, and natural language rationales. These questions require long reasoning steps while the topic is limited to conic sections. It could be used to evaluate models with 2 tasks: semantic parsing and mathematical question answering (mathQA).

ConstructiveBench

Enumerate–Conjecture–Prove: Formally Solving Answer-Construction Problem in Math Competitions We release the ConstructiveBench dataset as part of our Enumerate–Conjecture–Prove (ECP) paper. It enables benchmarking automated reasoning systems on answer-construction math problems using Lean 4. Source Repository: https://github.com/JackSun200312/ECP Description This dataset (constructivebench.json) contains curated Olympiad-style math problems along with metadata and aligned Lean 4 formalizations. Each entry includes: Problem statement Category (e.g., Algebra, Combinatorics) Source (e.g., IMO 2011) Formal answer in Lean Full formal theorem Answer-construction alignment parts (header, answer, theorem, and theorem without answer) Example Entry { "name": "IMO2011SLC4", "category": "Combinatorics", "source": "IMO/2011", "problem": "...", "answer": "The greatest such number k is 3", "formalization": "...", "is_formalized": true, ... }

출처: Papers with Code · CC BY-SA 4.0. 아카이브 자료와 새로 수집한 논문은 별도로 관리합니다.