Papers with Code · CC BY-SA 4.0

데이터셋 탐색

데이터셋의 설명·홈페이지를 찾고, 관련 태스크의 평가 기록을 살펴보세요.

관련 논문 125편

LUNA

LUNA 설명 보기

The LUNA challenges provide datasets for automatic nodule detection algorithms using the largest publicly available reference database of chest CT scans, the LIDC-IDRI data set. In LUNA16, participants develop their algorithm and upload their predictions on 888 CT scans in one of the two tracks: 1) the complete nodule detection track where a complete CAD system should be developed, or 2) the false positive reduction track where a provided set of nodule candidates should be classified. Source: Validation, comparison, and combination of algorithms for automatic detection of pulmonary nodules in computed tomography images: the LUNA16 challenge
관련 논문 125편

QuickDraw

QuickDraw 설명 보기

Click to add a brief description of the dataset (Markdown and LaTeX enabled). Provide: * a high-level explanation of the dataset characteristics * explain motivations and summary of its content * potential use cases of the dataset

관련 논문 125편

Yelp2018

Yelp2018 설명 보기

The Yelp2018 dataset is adopted from the 2018 edition of the yelp challenge. Wherein local businesses like restaurants and bars are viewed as items. We use the same 10-core setting in order to ensure data quality.

관련 논문 124편

MSRA Text Detection 500 Database

MSRA-TD500
MSRA-TD500 설명 보기

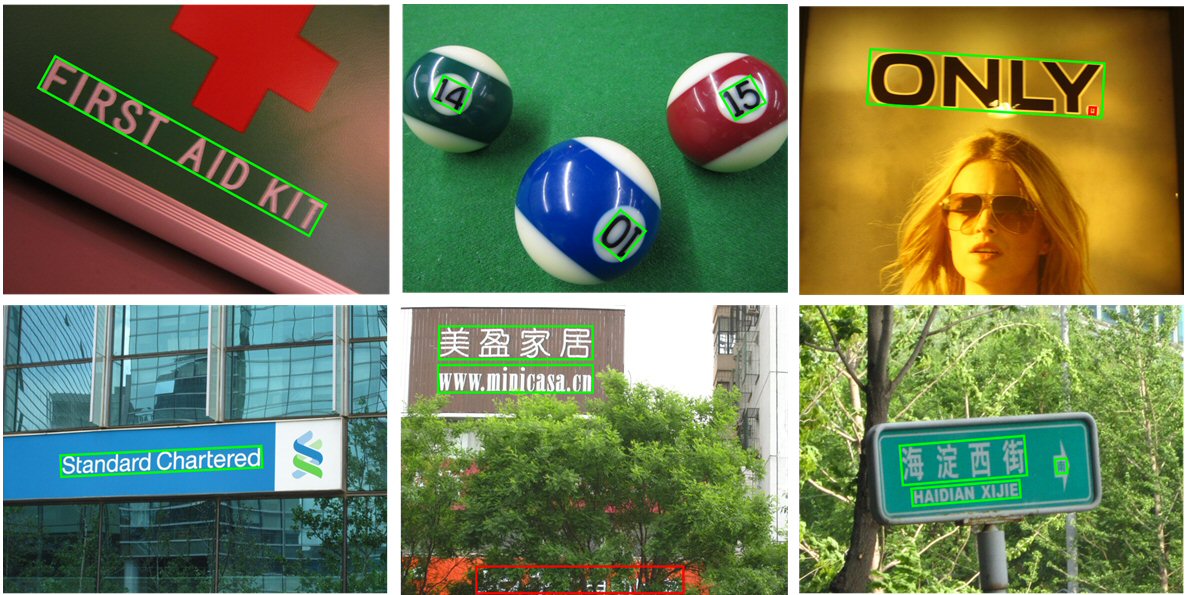
The MSRA-TD500 dataset is a text detection dataset that contains 300 training images and 200 test images. Text regions are arbitrarily orientated and annotated at sentence level. Different from the other datasets, it contains both English and Chinese text. Source: Detecting Text in the Wild with Deep Character Embedding Network Image Source: http://www.iapr-tc11.org/mediawiki/images/MSRA-TD500_Example.jpg

관련 논문 124편

Microsoft Academic Graph

Microsoft Academic Graph 설명 보기

The Microsoft Academic Graph is a heterogeneous graph containing scientific publication records, citation relationships between those publications, as well as authors, institutions, journals, conferences, and fields of study. Documentation

관련 논문 124편

North Campus Long-Term Vision and LiDAR

NCLT
NCLT 설명 보기

The NCLT dataset is a large scale, long-term autonomy dataset for robotics research collected on the University of Michigan’s North Campus. The dataset consists of omnidirectional imagery, 3D lidar, planar lidar, GPS, and proprioceptive sensors for odometry collected using a Segway robot. The dataset was collected to facilitate research focusing on long-term autonomous operation in changing environments. The dataset is comprised of 27 sessions spaced approximately biweekly over the course of 15 months. The sessions repeatedly explore the campus, both indoors and outdoors, on varying trajectories, and at different times of the day across all four seasons. This allows the dataset to capture many challenging elements including: moving obstacles (e.g., pedestrians, bicyclists, and cars), changing lighting, varying viewpoint, seasonal and weather changes (e.g., falling leaves and snow), and long-term structural changes caused by construction projects. Source: http://robots.engin.umich.edu/nclt/nclt.pdf Image Source: http://robots.engin.umich.edu/nclt/

관련 논문 123편

Contextualized Affect Representations for Emotion Recognition

CARER
CARER 설명 보기

CARER is an emotion dataset collected through noisy labels, annotated via distant supervision as in (Go et al., 2009). The subset of data provided here corresponds to the six emotions variant described in the paper. The six emotions are anger, fear, joy, love, sadness, and surprise. Source: CARER: Contextualized Affect Representations for Emotion Recognition

관련 논문 123편

JFT-300M

JFT-300M 설명 보기

JFT-300M is an internal Google dataset used for training image classification models. Images are labeled using an algorithm that uses complex mixture of raw web signals, connections between web-pages and user feedback. This results in over one billion labels for the 300M images (a single image can have multiple labels). Of the billion image labels, approximately 375M are selected via an algorithm that aims to maximize label precision of selected images.

관련 논문 123편

PubLayNet

PubLayNet 설명 보기

PubLayNet is a dataset for document layout analysis by automatically matching the XML representations and the content of over 1 million PDF articles that are publicly available on PubMed Central. The size of the dataset is comparable to established computer vision datasets, containing over 360 thousand document images, where typical document layout elements are annotated. Source: PubLayNet: largest dataset ever for document layout analysis

관련 논문 122편

Bias Benchmark for QA

BBQ
BBQ 설명 보기

Bias Benchmark for QA (BBQ) is a dataset consisting of question-sets constructed by the authors that highlight attested social biases against people belonging to protected classes along nine different social dimensions relevant for U.S. English-speaking contexts.

관련 논문 122편

LibriMix

LibriMix 설명 보기

LibriMix is an open-source alternative to wsj0-2mix. Based on LibriSpeech, LibriMix consists of two- or three-speaker mixtures combined with ambient noise samples from WHAM!. Source: LibriMix: An Open-Source Dataset for Generalizable Speech Separation

관련 논문 122편

MAth Word ProblemS

MAWPS
MAWPS 설명 보기

MAWPS is an online repository of Math Word Problems, to provide a unified testbed to evaluate different algorithms. MAWPS allows for the automatic construction of datasets with particular characteristics, providing tools for tuning the lexical and template overlap of a dataset as well as for filtering ungrammatical problems from web-sourced corpora. The online nature of this repository facilitates easy community contribution. Amassed 3,320 problems, including the full datasets used in several previous works.

관련 논문 121편

ETH3D

ETH3D 설명 보기

ETHD is a multi-view stereo benchmark / 3D reconstruction benchmark that covers a variety of indoor and outdoor scenes. Ground truth geometry has been obtained using a high-precision laser scanner. A DSLR camera as well as a synchronized multi-camera rig with varying field-of-view was used to capture images. Source: A Multi-View Stereo Benchmark With High-Resolution Images and Multi-Camera Videos

관련 논문 121편

GENIA

GENIA 설명 보기

The GENIA corpus is the primary collection of biomedical literature compiled and annotated within the scope of the GENIA project. The corpus was created to support the development and evaluation of information extraction and text mining systems for the domain of molecular biology. The corpus contains 1,999 Medline abstracts, selected using a PubMed query for the three MeSH terms “human”, “blood cells”, and “transcription factors”. The corpus has been annotated with various levels of linguistic and semantic information. The primary categories of annotation in the GENIA corpus and the corresponding subcorpora are: * Part-of-Speech annotation * Constituency (phrase structure) syntactic annotation * Term annotation * Event annotation * Relation annotation * Coreference annotation Source: http://www.geniaproject.org/genia-corpus Image Source: http://www.geniaproject.org/genia-corpus

관련 논문 121편

Permuted MNIST

Permuted MNIST 설명 보기

Permuted MNIST is an MNIST variant that consists of 70,000 images of handwritten digits from 0 to 9, where 60,000 images are used for training, and 10,000 images for test. The difference of this dataset from the original MNIST is that each of the ten tasks is the multi-class classification of a different random permutation of the input pixels. Source: Lifelong Learning with Dynamically Expandable Networks Image Source: https://arxiv.org/pdf/1810.12488.pdf

관련 논문 120편

Georgia Tech Egocentric Activity

GTEA
GTEA 설명 보기

The Georgia Tech Egocentric Activities (GTEA) dataset contains seven types of daily activities such as making sandwich, tea, or coffee. Each activity is performed by four different people, thus totally 28 videos. For each video, there are about 20 fine-grained action instances such as take bread, pour ketchup, in approximately one minute. Source: TricorNet: A Hybrid Temporal Convolutional and Recurrent Network for Video Action Segmentation Image Source: http://cbs.ic.gatech.edu/fpv/

관련 논문 120편

Raindrop

Raindrop 설명 보기

Raindrop is a set of image pairs, where each pair contains exactly the same background scene, yet one is degraded by raindrops and the other one is free from raindrops. To obtain this, the images are captured through two pieces of exactly the same glass: one sprayed with water, and the other is left clean. The dataset consists of 1,119 pairs of images, with various background scenes and raindrops. They were captured with a Sony A6000 and a Canon EOS 60. Source: Attentive Generative Adversarial Network for Raindrop Removal from a Single Image

관련 논문 120편

Swarm Heuristics based Adaptive and Penalized Estimation of Splines

SHAPES
SHAPES 설명 보기

SHAPES is a dataset of synthetic images designed to benchmark systems for understanding of spatial and logical relations among multiple objects. The dataset consists of complex questions about arrangements of colored shapes. The questions are built around compositions of concepts and relations, e.g. Is there a red shape above a circle? or Is a red shape blue?. Questions contain between two and four attributes, object types, or relationships. There are 244 questions and 15,616 images in total, with all questions having a yes and no answer (and corresponding supporting image). This eliminates the risk of learning biases. Each image is a 30×30 RGB image depicting a 3×3 grid of objects. Each object is characterized by shape (circle, square, triangle), colour (red, green, blue) and size (small, big). Source: Visual Question Answering: A Survey of Methods and Datasets Image Source: https://github.com/ronghanghu/n2nmn#train-and-evaluate-on-the-shapes-dataset

관련 논문 120편

Social Interaction QA

SIQA
SIQA 설명 보기

Social Interaction QA (SIQA) is a question-answering benchmark for testing social commonsense intelligence. Contrary to many prior benchmarks that focus on physical or taxonomic knowledge, Social IQa focuses on reasoning about people’s actions and their social implications. For example, given an action like "Jesse saw a concert" and a question like "Why did Jesse do this?", humans can easily infer that Jesse wanted "to see their favorite performer" or "to enjoy the music", and not "to see what's happening inside" or "to see if it works". The actions in Social IQa span a wide variety of social situations, and answer candidates contain both human-curated answers and adversarially-filtered machine-generated candidates. Social IQa contains over 37,000 QA pairs for evaluating models’ abilities to reason about the social implications of everyday events and situations. Source: Social IQA Image Source: https://arxiv.org/pdf/1904.09728.pdf

관련 논문 120편

SimpleQuestions

SimpleQuestions 설명 보기

SimpleQuestions is a large-scale factoid question answering dataset. It consists of 108,442 natural language questions, each paired with a corresponding fact from Freebase knowledge base. Each fact is a triple (subject, relation, object) and the answer to the question is always the object. The dataset is divided into training, validation, and test sets with 75,910, 10,845 and 21,687 questions respectively. Source: Hierarchical Memory Networks Image Source: https://paperswithcode.com/paper/large-scale-simple-question-answering-with/

관련 논문 120편

shape bias

shape bias 설명 보기

The 'shape bias' dataset was introduced in Geirhos et al. (ICLR 2019) and consists of 224x224 images with conflicting texture and shape information (e.g., cat shape with elephant texture). This is used to measure the shape vs. texture bias of image classifiers.

관련 논문 118편

MAESTRO

MAESTRO 설명 보기

The MAESTRO dataset contains over 200 hours of paired audio and MIDI recordings from ten years of International Piano-e-Competition. The MIDI data includes key strike velocities and sustain/sostenuto/una corda pedal positions. Audio and MIDI files are aligned with ∼3 ms accuracy and sliced to individual musical pieces, which are annotated with composer, title, and year of performance. Uncompressed audio is of CD quality or higher (44.1–48 kHz 16-bit PCM stereo). Source: https://magenta.tensorflow.org/datasets/maestro Image Source: https://www.researchgate.net/figure/Results-generated-with-the-MAESTRO-dataset_fig3_333392458

관련 논문 118편

Video And TEXt

VATEX
VATEX 설명 보기

VATEX is multilingual, large, linguistically complex, and diverse dataset in terms of both video and natural language descriptions. It has two tasks for video-and-language research: (1) Multilingual Video Captioning, aimed at describing a video in various languages with a compact unified captioning model, and (2) Video-guided Machine Translation, to translate a source language description into the target language using the video information as additional spatiotemporal context. Source: https://arxiv.org/pdf/1904.03493.pdf Image Source: https://arxiv.org/pdf/1904.03493.pdf

관련 논문 117편

AFLW2000-3D

AFLW2000-3D 설명 보기

AFLW2000-3D is a dataset of 2000 images that have been annotated with image-level 68-point 3D facial landmarks. This dataset is used for evaluation of 3D facial landmark detection models. The head poses are very diverse and often hard to be detected by a CNN-based face detector. Source: https://www.tensorflow.org/datasets/catalog/aflw2k3d Image Source: http://www.cbsr.ia.ac.cn/users/xiangyuzhu/projects/3DDFA/main.htm

관련 논문 117편

FLoRes-200

FLoRes-200 설명 보기

FLoRes-200 doubles the existing language coverage of FLoRes-101. Given the nature of the new languages, which have less standardization and require more specialized professional translations, the verification process became more complex. This required modifications to the translation workflow. FLoRes-200 has several languages which were not translated from English. Specifically, several languages were translated from Spanish, French, Russian, and Modern Standard Arabic.

관련 논문 117편

KILT Benchmark

KILT
KILT 설명 보기

KILT (Knowledge Intensive Language Tasks) is a benchmark consisting of 11 datasets representing 5 types of tasks: * Fact-checking (FEVER), * Entity linking (AIDA CoNLL-YAGO, WNED-WIKI, WNED-CWEB), * Slot filling (T-Rex, Zero Shot RE), * Open domain QA (Natural Questions, HotpotQA, TriviaQA, ELI5), * Dialog generation (Wizard of Wikipedia). All these datasets have been grounded in a single pre-processed wikipedia snapshot, allowing for fairer and more consistent evaluation as well as enabling new task setups such as multitask and transfer learning. Source: KILT Benchmarking

관련 논문 117편

The Kvasir Dataset

Kvasir
Kvasir 설명 보기

The KVASIR Dataset was released as part of the medical multimedia challenge presented by MediaEval. It is based on images obtained from the GI tract via an endoscopy procedure. The dataset is composed of images that are annotated and verified by medical doctors, and captures 8 different classes. The classes are based on three anatomical landmarks (z-line, pylorus, cecum), three pathological findings (esophagitis, polyps, ulcerative colitis) and two other classes (dyed and lifted polyps, dyed resection margins) related to the polyp removal process. Overall, the dataset contains 8,000 endoscopic images, with 1,000 image examples per class. Source: Two-Stream Deep Feature Modelling for Automated Video Endoscopy Data Analysis Image Source: https://datasets.simula.no/kvasir/

관련 논문 117편

SNLI-VE

SNLI-VE 설명 보기

Visual Entailment (VE) consists of image-sentence pairs whereby a premise is defined by an image, rather than a natural language sentence as in traditional Textual Entailment tasks. The goal of a trained VE model is to predict whether the image semantically entails the text. SNLI-VE is a dataset for VE which is based on the Stanford Natural Language Inference corpus and Flickr30k dataset. Source: https://github.com/necla-ml/SNLI-VE

관련 논문 117편

Something-Something V1

Something-Something V1 설명 보기

The 20BN-SOMETHING-SOMETHING dataset is a large collection of labeled video clips that show humans performing pre-defined basic actions with everyday objects. The dataset was created by a large number of crowd workers. It allows machine learning models to develop fine-grained understanding of basic actions that occur in the physical world. It contains 108,499 videos, with 86,017 in the training set, 11,522 in the validation set and 10,960 in the test set. There are 174 labels. ⚠️ Attention: This is the outdated V1 of the dataset. V2 is available here. Source: https://20bn.com/datasets/something-something/v1 Image Source: https://20bn.com/datasets/something-something/v1

관련 논문 117편

T-REx

T-REx 설명 보기

A dataset of large scale alignments between Wikipedia abstracts and Wikidata triples. T-REx consists of 11 million triples aligned with 3.09 million Wikipedia abstracts (6.2 million sentences). Source: T-REx: A Large Scale Alignment of Natural Language with Knowledge Base Triples

관련 논문 117편

Vggface2: A dataset for recognising faces across pose and age

VGGFace2 Dataset
VGGFace2 Dataset 설명 보기

VGGFace2 is a large-scale face recognition dataset. Images are downloaded from Google Image Search and have large variations in pose, age, illumination, ethnicity and profession. VGGFace2 contains images from identities spanning a wide range of different ethnicities, accents, professions and ages. All face images are captured "in the wild", with pose and emotion variations and different lighting and occlusion conditions. Face distribution for different identities is varied, from 87 to 843, with an average of 362 images for each subject.

관련 논문 116편

A Visible-infrared Paired Dataset for Low-light Vision

LLVIP
LLVIP 설명 보기
  • Visible-infrared Paired Dataset for Low-light Vision * 30976 images (15488 pairs) * 24 dark scenes, 2 daytime scenes * Support for image-to-image translation (visible to infrared, or infrared to visible), visible and infrared image fusion, low-light pedestrian detection, and infrared pedestrian detection * (The original image and video pairs (before registration) of LLVIP are also released!)
관련 논문 116편

MRQA

MRQA 설명 보기

The MRQA (Machine Reading for Question Answering) dataset is a dataset for evaluating the generalization capabilities of reading comprehension systems. Source: MRQA 2019 Shared Task: Evaluating Generalization in Reading Comprehension

관련 논문 116편

PadChest

PadChest 설명 보기

PadChest is a labeled large-scale, high resolution chest x-ray dataset for the automated exploration of medical images along with their associated reports. This dataset includes more than 160,000 images obtained from 67,000 patients that were interpreted and reported by radiologists at Hospital San Juan Hospital (Spain) from 2009 to 2017, covering six different position views and additional information on image acquisition and patient demography. The reports were labeled with 174 different radiographic findings, 19 differential diagnoses and 104 anatomic locations organized as a hierarchical taxonomy and mapped onto standard Unified Medical Language System (UMLS) terminology. Of these reports, 27% were manually annotated by trained physicians and the remaining set was labeled using a supervised method based on a recurrent neural network with attention mechanisms. The labels generated were then validated in an independent test set achieving a 0.93 Micro-F1 score.

관련 논문 115편

CC100

CC100 설명 보기

This corpus comprises of monolingual data for 100+ languages and also includes data for romanized languages. This was constructed using the urls and paragraph indices provided by the CC-Net repository by processing January-December 2018 Commoncrawl snapshots. Each file comprises of documents separated by double-newlines and paragraphs within the same document separated by a newline. The data is generated using the open source CC-Net repository. Source: Unsupervised Cross-lingual Representation Learning at Scale

관련 논문 115편

Categorical Subjective Image Quality

CSIQ
CSIQ 설명 보기

The CSIQ database consists of 30 original images, each is distorted using six different types of distortions at four to five different levels of distortion. CSIQ images are subjectively rated base on a linear displacement of the images across four calibrated LCD monitors placed side by side with equal viewing distance to the observer. The database contains 5000 subjective ratings from 35 different observers, and ratings are reported in the form of DMOS.

관련 논문 115편

EMBER

EMBER 설명 보기

A labeled benchmark dataset for training machine learning models to statically detect malicious Windows portable executable files. The dataset includes features extracted from 1.1M binary files: 900K training samples (300K malicious, 300K benign, 300K unlabeled) and 200K test samples (100K malicious, 100K benign). Source: EMBER: An Open Dataset for Training Static PE Malware Machine Learning Models

관련 논문 115편

Lip Reading Sentences 2

LRS2
LRS2 설명 보기

The Oxford-BBC Lip Reading Sentences 2 (LRS2) dataset is one of the largest publicly available datasets for lip reading sentences in-the-wild. The database consists of mainly news and talk shows from BBC programs. Each sentence is up to 100 characters in length. The training, validation and test sets are divided according to broadcast date. It is a challenging set since it contains thousands of speakers without speaker labels and large variation in head pose. The pre-training set contains 96,318 utterances, the training set contains 45,839 utterances, the validation set contains 1,082 utterances and the test set contains 1,242 utterances. Source: Audio-visual Recognition of Overlapped speech for the LRS2 dataset Image Source: https://www.robots.ox.ac.uk/~vgg/data/lip_reading/lrs2.html

관련 논문 115편

The Stack

The Stack 설명 보기

The Stack contains over 3TB of permissively-licensed source code files covering 30 programming languages crawled from GitHub. The dataset was created as part of the BigCode Project, an open scientific collaboration working on the responsible development of Large Language Models for Code (Code LLMs). Source: https://huggingface.co/datasets/bigcode/the-stack Image Source: https://huggingface.co/datasets/bigcode/the-stack

관련 논문 115편

The Highway Drone Dataset Naturalistic Trajectories of 110 500 Vehicles Recorded at German Highways

highD Dataset
highD Dataset 설명 보기

The highD dataset is a new dataset of naturalistic vehicle trajectories recorded on German highways. Using a drone, typical limitations of established traffic data collection methods such as occlusions are overcome by the aerial perspective. Traffic was recorded at six different locations and includes more than 110 500 vehicles. Each vehicle's trajectory, including vehicle type, size and manoeuvres, is automatically extracted. Using state-of-the-art computer vision algorithms, the positioning error is typically less than ten centimeters. Although the dataset was created for the safety validation of highly automated vehicles, it is also suitable for many other tasks such as the analysis of traffic patterns or the parameterization of driver models.

관련 논문 114편

Caltech Occluded Faces in the Wild

COFW
COFW 설명 보기

The Caltech Occluded Faces in the Wild (COFW) dataset is designed to present faces in real-world conditions. Faces show large variations in shape and occlusions due to differences in pose, expression, use of accessories such as sunglasses and hats and interactions with objects (e.g. food, hands, microphones, etc.). All images were hand annotated using the same 29 landmarks as in LFPW. Both the landmark positions as well as their occluded/unoccluded state were annotated. The faces are occluded to different degrees, with large variations in the type of occlusions encountered. COFW has an average occlusion of over 23. Source: http://www.vision.caltech.edu/xpburgos/ICCV13/#dataset Image Source: http://www.vision.caltech.edu/xpburgos/ICCV13/#dataset

관련 논문 114편

MCTest

MCTest 설명 보기

MCTest is a freely available set of stories and associated questions intended for research on the machine comprehension of text. MCTest requires machines to answer multiple-choice reading comprehension questions about fictional stories, directly tackling the high-level goal of open-domain machine comprehension. Source: MCTest: A Challenge Dataset for the Open-Domain Machine Comprehension of Text Image Source: Richardson et al

관련 논문 114편

Question Answering via Sentence Composition

QASC
QASC 설명 보기

QASC is a question-answering dataset with a focus on sentence composition. It consists of 9,980 8-way multiple-choice questions about grade school science (8,134 train, 926 dev, 920 test), and comes with a corpus of 17M sentences. Source: Allen Institute for AI